Keep your technology
working, improving,
and delivering value.

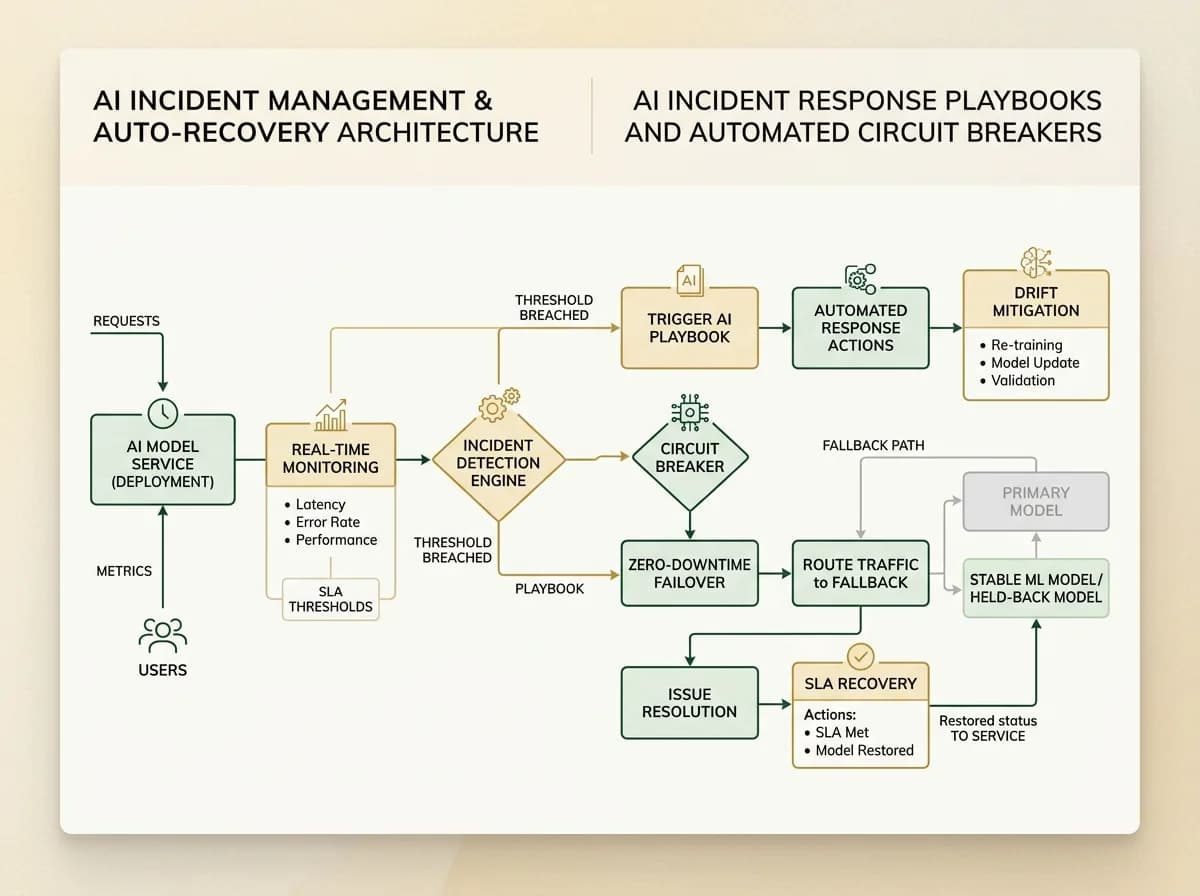
Launching an AI solution is only Day One. In production, models drift, traffic surges, and token costs escalate. We provide 24/7 Managed AI and MLOps that keep enterprise environments reliable, secure, cost-governed, and continuously optimized.

99.99%
Uptime SLA
−40%
Inference Spend
< 15m
Incident MTTR
Zero
Silent Drift

Managed AI Operations Cockpit

01
Distributed Tracing· Monitor API latency, model token queues & cluster health
ACTIVE
02
Breach Detection· Instant anomaly trigger within 60s of SLA deviation
03
Auto-Routing· Dynamic load diversion across multi-region Kubernetes nodes
04
SLA Assurance· Nominal latency restored with zero dropped user requests
LIVE:SYS: All 3 cluster nodes reporting healthy (latency P99: 118ms)
24/7 SRE
Projected SLA: 99.99% SLA · Zero Outages
P99: 118ms · 3 Clusters Healthy
Day-2 Operations & Ongoing Reliability

Launch is only the beginning. Management creates lasting value.

We manage the complete operational lifecycle—turning your production deployment into an engine of continuous improvement. Three core pillars keep your systems reliable, optimized, and compliant.
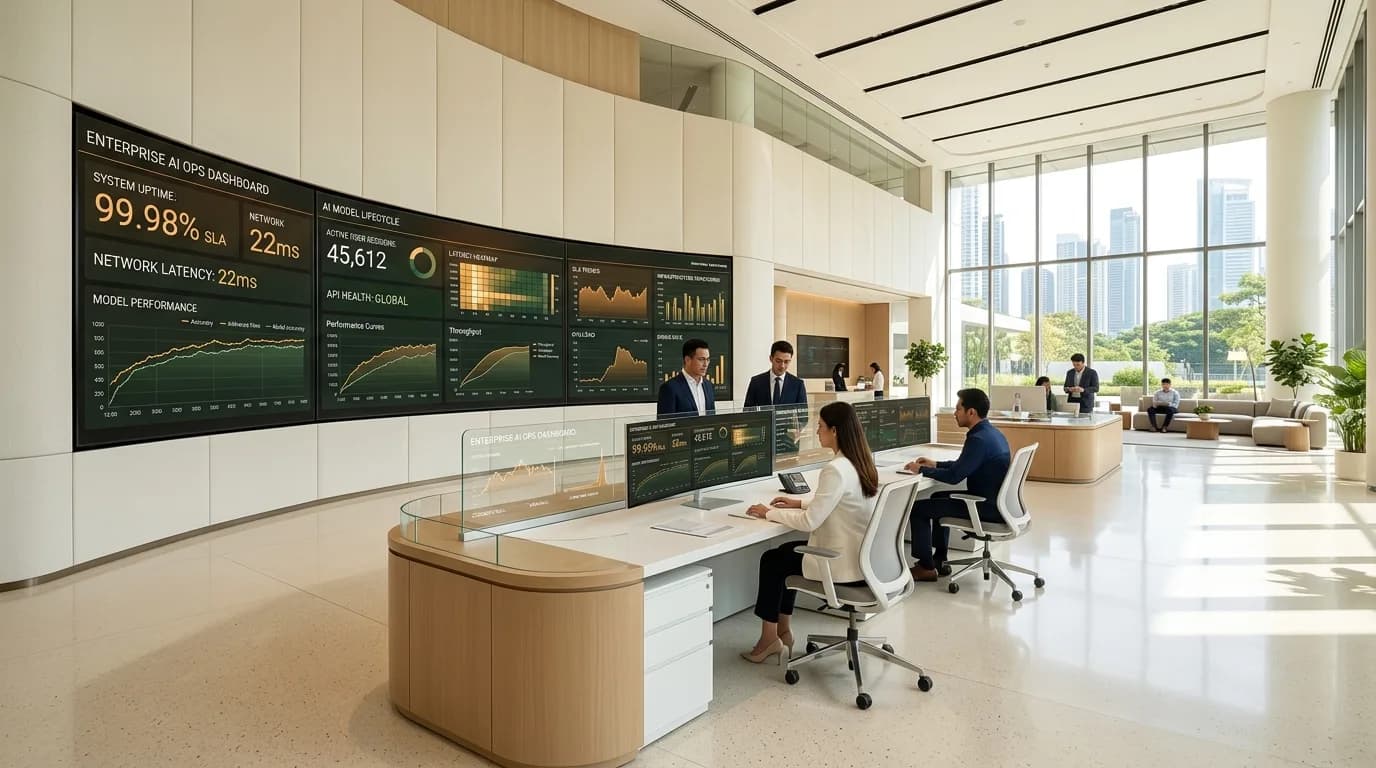
Enterprise AI operations center with real-time telemetry, model lifecycle monitoring, and SLA health dashboards in daylight
24/7 Enterprise AI Operations Center
Active Telemetry & SRE Infrastructure

Autonomous Guardrails, Model Drift Monitoring & Zero-Downtime Governance

Continuous Monitoring
Active
Real-time API latency & P99 error rate tracking
Model accuracy and hallucination rate telemetry
Token burn monitoring and budget alert triggers
Multi-cloud resource utilization & auto-scaling probes
Proactive Optimization
Active
Semantic cache tuning to slash inference overhead
Prompt template A/B testing from implicit feedback
Multi-tier model routing for low-cost tasks
GPU rightsizing and spot-instance orchestration
Runtime Governance
Active
Secret rotation and PII masking compliance
Immutable audit logs for all AI decisions
Regulatory alignment with EU AI Act & SOC2
Automated canary rollbacks upon drift detection
02 — Core Capabilities Architecture

The Autonomous Operations Fabric:
Everything required to operate AI at scale.

We unite deep MLOps, cloud site reliability engineering (SRE), FinOps cost governance, and active security management under unified operational runbooks.

01 / 08
0102030405060708
Telemetry01ACTIVE
SIGNAL:Distributed APM stream verified · 1,420 req/s
Pillar 01 · Telemetry99.99% Uptime · P99: 18ms

24/7 Production Observability

Real-time synthetic and live monitoring across application frontends, API latency, model token queues, inference accuracy, and cloud cluster resource utilization.

Continuous Telemetry StreamSub-Millisecond Resolution
Operational Runbook Spectrum · Select capability
01
24/7 Production Observability
→
02
Model Drift & Accuracy Management
→
03
FinOps & Inference Cost Governance
→
04
Cloud Infrastructure & SRE Operations
→
05
End-to-End Dependency Tracing
→
06
Continuous Prompt & Workflow Tuning
→
07
Active Security & Runtime Governance
→
08
Multi-Workload Portfolio Management
→
FinOps Token Architecture

Intelligent Model Cascading & Semantic Caching

Stop sending every prompt to expensive frontier models. Our intelligent gateway intercepts recurring queries with sub-10ms semantic vector caches and routes lightweight tasks to compact models.

−40.8%
Monthly API Bill Slash
$4820
Est. 7-Day Net Savings
INCOMING:“Customer account status retrieval”
6ms
Tier 0: Semantic Cache (Vector DB)
0ms Token Cost · 99.4% Cosine Similarity Match
ACTIVE ROUTE (100% SAVED)
Tier 1: High-Speed SLM (8B / Private Endpoint)
Ultra-Low Latency · $0.001 / 1K Tokens
24% Volume
Tier 2: Frontier Reasoning Model (GPT-4o / Claude 3.5)
Full Context Reasoning · Reserved for Deep Edge Tasks
8% Volume
Net Execution Cost: $0.000Cost Avoidance: +$0.040 saved
03 — Environment Coverage Architecture

Managing every modern AI workload.

From commercial foundation models to custom predictive ML algorithms running on dedicated multi-region clusters, our operational fabric guarantees enterprise SLAs.

01

Generative AI & LLMs

99.99% SLA

Prompt Caching & Hallucination Defense

02

AI Assistants & Agents

Active Loop Monitor

Tool Execution & Multi-Step Workflows

03

Predictive ML Models

Zero Drift

Data Drift & Feature Store Health

04

Intelligent Automation

Queue nominal

API Resilience & Robotic Worker Queues

05

Enterprise Knowledge & RAG

Index Fresh

Index Freshness & Retrieval Relevance

06

Custom Cloud AI Platforms

3/3 Nodes Healthy

GPU Clusters & Multi-Region SRE

6 Production AI Topologies
Workload 01 · Foundation Models99.99% SLA · P99: 112ms

Prompt Caching & Hallucination Defense

Tracking token usage, answer relevance, latency SLAs, response toxicity, and model version updates across internal and customer apps.
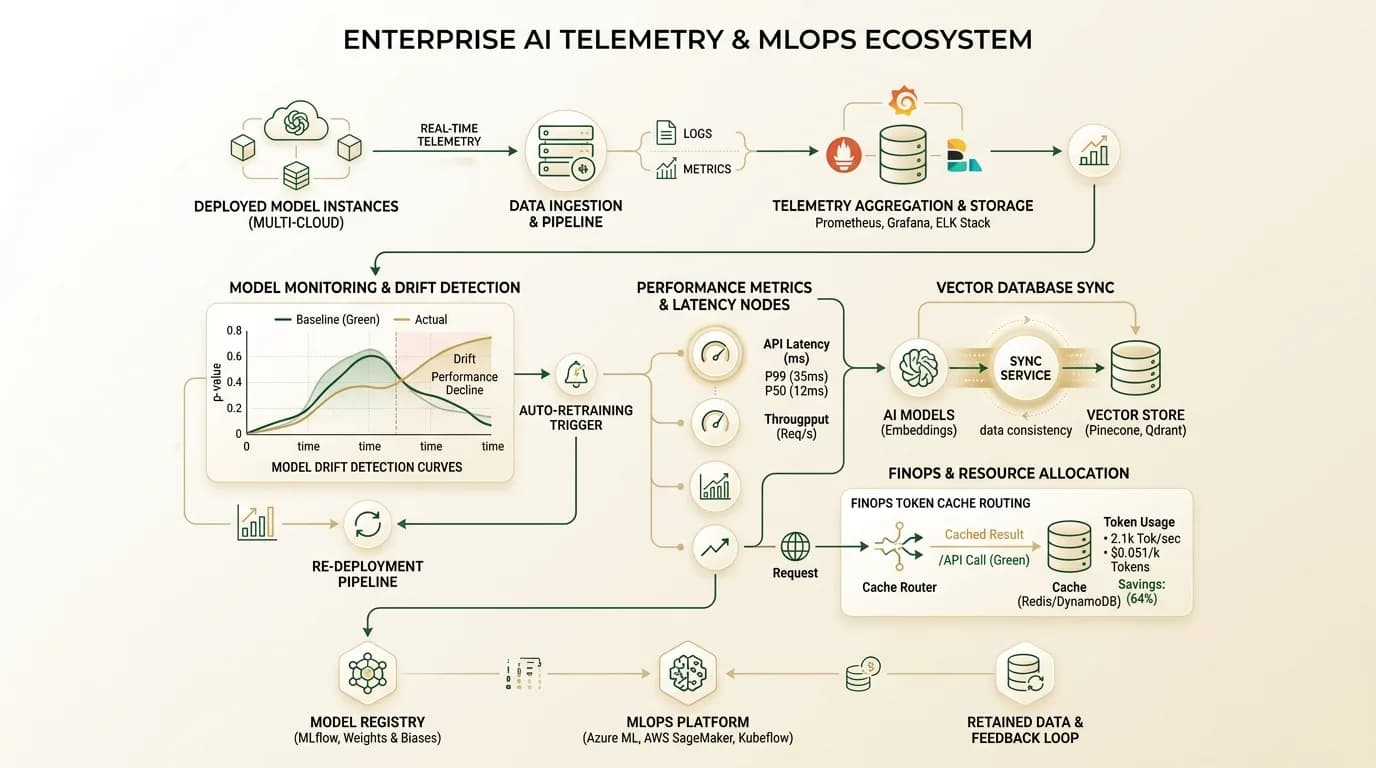
Active Systems TopologyContinuous Observability Link
GPT-4o⇢
Claude 3.5⇢
Llama 3 70B⇢
Semantic Cache
TELEMETRY:Token Cache: 68% Hit · Hallucination Guard: Active · Latency: 112ms
100% OK
Enterprise AI Telemetry and MLOps ecosystem diagram showing model drift detection, latency nodes, vector DB sync, and FinOps token cache routing
Enterprise AI Systems Topology & MLOps Interconnect
04 — Operational Transformation

From reactive firefighting to continuous optimization.

Eliminate unbudgeted cloud spikes, silent model decay, and midnight engineer pages with systematic, SLA-backed Day-2 operations.

Concern
✕ Unmanaged Baseline
✓ Waypoint Managed AI
Incident Discovery
—Users complain hours after the outage begins
✓Automated telemetry alerts within 60 seconds of anomaly
Model Accuracy
—Silent drift degrades predictions unnoticed
✓Continuous drift testing with auto-retraining triggers
Cloud Costs
—Surprise token bills at month-end
✓Daily FinOps dashboards, semantic caching and automated limits
Team Bandwidth
—Core engineers pulled to debug production fires
✓Engineering stays 100% focused on innovation roadmap
Security & Compliance
—Patches and key rotations handled ad-hoc
✓Automated rotation schedules, SOC2 and audit trail logging
05 — Operating Framework Methodology

Disciplined path to operational excellence.

A battle-tested 8-stage methodology designed to stabilize, govern, and continuously refine your production environment.

01
Assess
02
Monitor
03
Stabilize
04
Optimize
05
Maintain
06
Improve
07
Scale
08
Govern
Stage 02 · Real-Time TelemetrySub-Second Telemetry

Monitor: Real-Time Telemetry

Instrument APM distributed tracing, custom model metrics, and FinOps telemetry.

Core Operational Output
✓Full-Stack Observability Suite
Interactive Operational Infinity Engine
Click node to inspect
ENTERPRISEManaged AI● 24/7 SRE LIVECONTINUOUSValue Creation⇄ LEARNING LOOP01Assess02Monitor03Stabilize04Optimize05Maintain06Improve07Scale08GovernUPTIME SLA99.99%FINOPS SAVINGS−40% TOKENSSOC2AUDIT OK98.4%ACCURACY
STAGE 02Monitor24/7 Telemetry
Target: P99: 18ms
Interactive Figure 5.1: Waypoint Autonomous Lifecycle Infinity EngineClick any of the 8 nodes to inspect active operational deliverables
Live Observability & Self-Healing Loop

Continuous Telemetry & Statistical Drift Defense

01Healthy
API Gateway
18ms1,420 req/s
02Optimal
Inference Engine
94ms48 GPUs active
03Synced
Drift Monitor
Real-timeScore: 0.014
04Fresh
Vector RAG Store
12msSync < 2m ago
Baseline Model Curve Production Stream
Sampling Interval: 1s
P-VALUE: 0.94 · SAFE ZONE
Autonomous Recovery MTTR
< 4.2 Seconds

Automated rollback & dynamic routing kicks in with zero human delay.

Current Prediction Confidence
98.7% Stable

Continuous evaluation against golden test datasets.

06 — Production Assurances

Enterprise SLAs and performance benchmarks.

Rigorous financial and performance commitments governed by real-time contract SLAs.

99.99%Guaranteed SLA
Production Uptime

Enterprise SLA backed by automated multi-zone failover and proactive SRE monitoring.

Contract Assurance● Verified
−40%Guaranteed SLA
Inference Cost Reduction

Drastic cloud and API token savings via semantic caching and model cascading.

Contract Assurance● Verified
< 15 MinGuaranteed SLA
Incident MTTR

Rapid mean-time-to-resolution supported by automated diagnostics and telemetry.

Contract Assurance● Verified
ZeroGuaranteed SLA
Unmonitored Drift

Continuous automated statistical drift testing ensures predictions never quietly decay.

Contract Assurance● Verified
+50%Guaranteed SLA
Internal Team Capacity

Frees in-house data scientists and engineers from 24/7 maintenance on-call duties.

Contract Assurance● Verified
Bi-WeeklyGuaranteed SLA
Optimization Sprints

Continuous tuning of prompts, parameters, and infrastructure throughout the contract.

Contract Assurance● Verified
07 — Why Waypoint

Technology shouldn't just run.
It should keep delivering.

We replace passive infrastructure monitoring with active, value-compounding AI engineering and enterprise SRE operations.
Beyond System Uptime
01
Value Realization
Compounding Enterprise ROI

Beyond System Uptime

Click or hover to inspectFlip ↺
Pillar 01 · Value RealizationVERIFIED

Beyond System Uptime

We don't just keep servers green. We actively optimize model accuracy, user satisfaction, and business ROI.
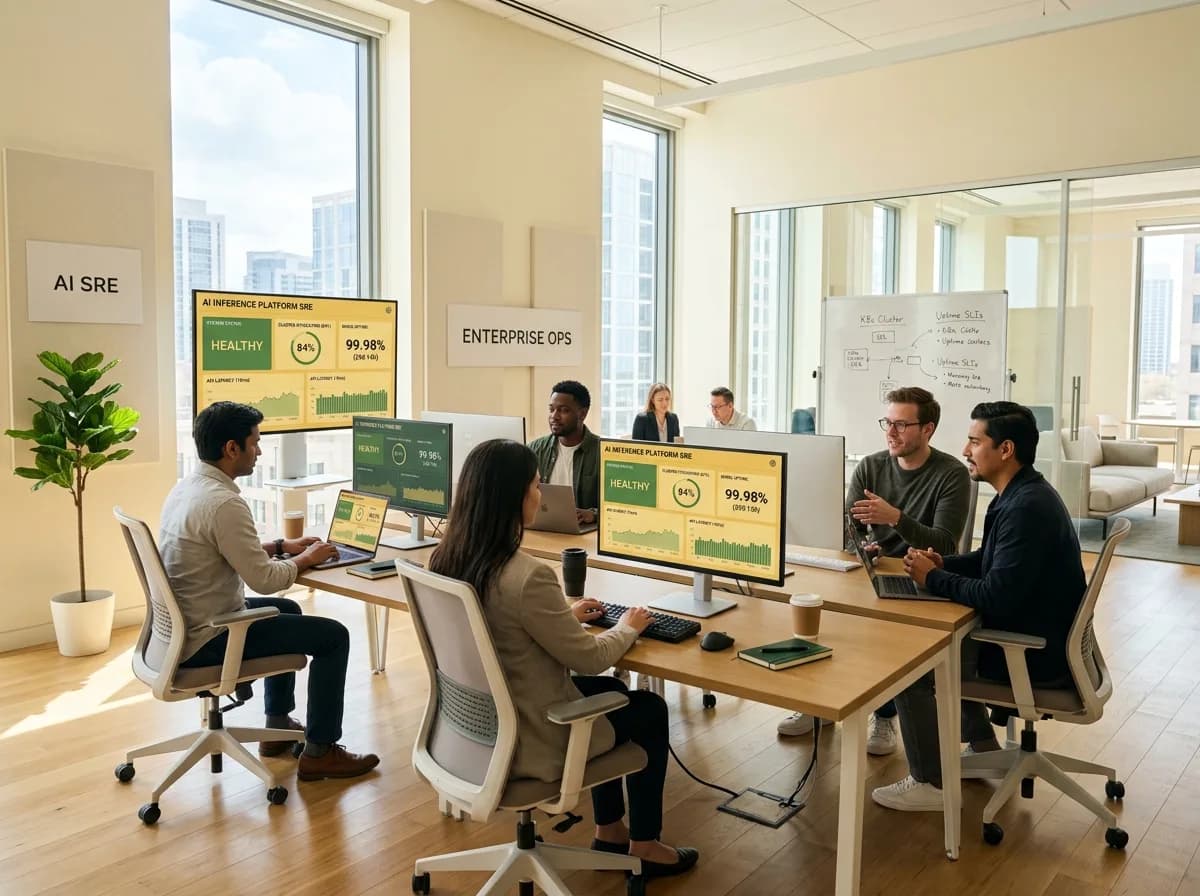
Core Commitment+3.4x Target ROI
Full-Stack AI & Cloud SRE
02
Site Reliability
GPU to Foundation LLMs

Full-Stack AI & Cloud SRE

Click or hover to inspectFlip ↺
Pillar 02 · Site ReliabilityVERIFIED

Full-Stack AI & Cloud SRE

Unified expertise spanning low-level GPU infrastructure, Kubernetes, vector databases, and LLM behavior.
Core Commitment99.99% Availability
Aggressive Cost Management
03
FinOps Governance
Logarithmic Spend Scaling

Aggressive Cost Management

Click or hover to inspectFlip ↺
Pillar 03 · FinOps GovernanceVERIFIED

Aggressive Cost Management

We continuously audit inference spend to ensure your costs scale logarithmically—not linearly.
Core Commitment−40% Inference Cost
Battle-Tested Incident Playbooks
04
Incident Playbooks
Deterministic Incident Runbooks

Battle-Tested Incident Playbooks

Click or hover to inspectFlip ↺
Pillar 04 · Incident PlaybooksVERIFIED

Battle-Tested Incident Playbooks

Pre-established runbooks for rate limits, model provider outages, silent data drift, and security exploits.
Core Commitment< 15 Min MTTR
Continuous Value Generation
05
Model Optimization
Active Learning Loops

Continuous Value Generation

Click or hover to inspectFlip ↺
Pillar 05 · Model OptimizationVERIFIED

Continuous Value Generation

Every production cycle is treated as a learning loop to make your models sharper, faster, and cheaper.
Core CommitmentBi-Weekly Tuning
Seamless Team Extension
06
Zero On-Call Drag
Dedicated Operations Division

Seamless Team Extension

Click or hover to inspectFlip ↺
Pillar 06 · Zero On-Call DragVERIFIED

Seamless Team Extension

We act as your dedicated AI operations and SRE division, allowing your core team to focus 100% on innovation.

Core Commitment+50% Dev Capacity
09 — 24/7 MANAGED MLOPS FAQANSWER ENGINE OPTIMIZED

Frequently asked managed AI & production operations questions.

Specific metrics regarding 24/7 endpoint surveillance, Kolmogorov-Smirnov drift detection, automated canary retraining pipelines, and 99.99% availability SLAs.

Our managed MLOps coverage includes 24/7 endpoint uptime, inference latency surveillance, GPU memory allocation, data drift detection, concept drift alerting, and automated anomaly escalation.

Continuous Operational Value

Ready to safeguard your production AI environment?

Don't let model drift, unexpected token bills, or silent degradation compromise your enterprise AI initiatives. We manage, stabilize, and continuously improve your production systems for the long haul.